DirectiveForge generates AI workflow kits for Claude Code and Cursor, then measures whether the skills it generated actually fire. On the pre-registered harness in the public repo, skill activation went from 0.33 to 0.83 with non-overlapping Wilson 95% confidence intervals over 30 runs per skill, measured for the v0.20.0 release on 2026-07-03. It ships MIT, and the raw per-trial records sit in the repo next to the summaries, so a stranger can recompute the numbers instead of trusting them.
The rules and skills people bolt onto coding agents mostly ship on feel. Someone writes a prompt, it reads better, it gets committed. I wanted to hand a kit to another developer with a published number attached to each piece: how often the skill fires on the inputs it should, and how often it stays quiet on the inputs it should not.
That meant two jobs, and the second one is the hard one. Generate the kit. Then prove the generated kit behaves, with evidence someone else can check without my help.
I ran it as a private lab before any of it was public. First commit 2026-03-29; 144 commits by the git check on 2026-07-06, and the public repository is a single squashed snapshot because the evidence had to be scrubbed before it could ship.
The evidence is bulky. The lab tree tracks 1,979 files and 428 MB on disk, and 296 MB of that is recorded measurement output under harness/results/. Those files are the product, and they are also full of local paths and client material, so redaction was a build step rather than a cleanup pass.
The measurement work was also compressed. The harness release, the delta run and the launch release all landed inside one day, 2026-07-03, across 21 commits between 14:14:09 and 20:41:01. That compression shows up again in the limits below.
The generator reads a codebase and writes the workflow files for it: rules, skills, commands, agents, MCP configuration and memory, installed into Claude Code or Cursor with one command. In the recorded runs it writes between 29 and 44 files, and every one of those runs left a manifest in the repo.
Around the generator sits the part that took the time.
The measurement is fixed before the run. The spec that defines each metric is committed before any result is collected, and the answer keys live in frozen fixture cards the generator never sees. Per-prompt and per-trial records are committed alongside the aggregates. That design was tested against me: an independent audit re-derived the 12 decision-skill trigger scores from the 120 raw router records and got 12 of 12 exact, with an identical pack-level F1 of 0.9661. F1 combines precision and recall into one number, which stops a skill from looking better by firing on everything.
Every rate ships as an interval, not a point. Each skill is run 30 times and reported as a Wilson 95% confidence interval, a range the true rate is likely to sit inside. A change only counts as an improvement when the two ranges do not overlap. The same audit recomputed all 14 published intervals from their own counts and matched them to four decimal places, and reproduced every activation count from the per-trial records.
The model that grades is graded first. Part of the scoring is done by a model reading outputs against a rubric. Before its verdicts counted, a second model re-judged the same outputs blind against a human-scored key: 18 of 20 exact, 20 of 20 within one point.
Publishing the evidence without leaking anything. The scrub gate fails the build on any hit, a hash bridge lets a reader confirm that a redacted file is the file it claims to be (67 artifacts carry one), and the scanner ships publicly while the list of identifying patterns stays on my machine. The public repository is a built snapshot produced by that pipeline, not a copy of the lab.
All figures below are from the 2026-07-03 delta run and its committed artifacts in the public repo.
Signal
Before
After
What it means
Skill activation
0.33
0.83
The 95% intervals do not overlap, so the gain is not noise
Planted-signal recall
0.90
1.00
Every deliberately planted case is caught
Link-gate false positives
13
0
The gate stopped firing on clean input
False content
4
0
No fabricated content left in the graded output
Judge calibration
none
18/20 exact, 20/20 within ±1
The grader was checked before its verdicts counted
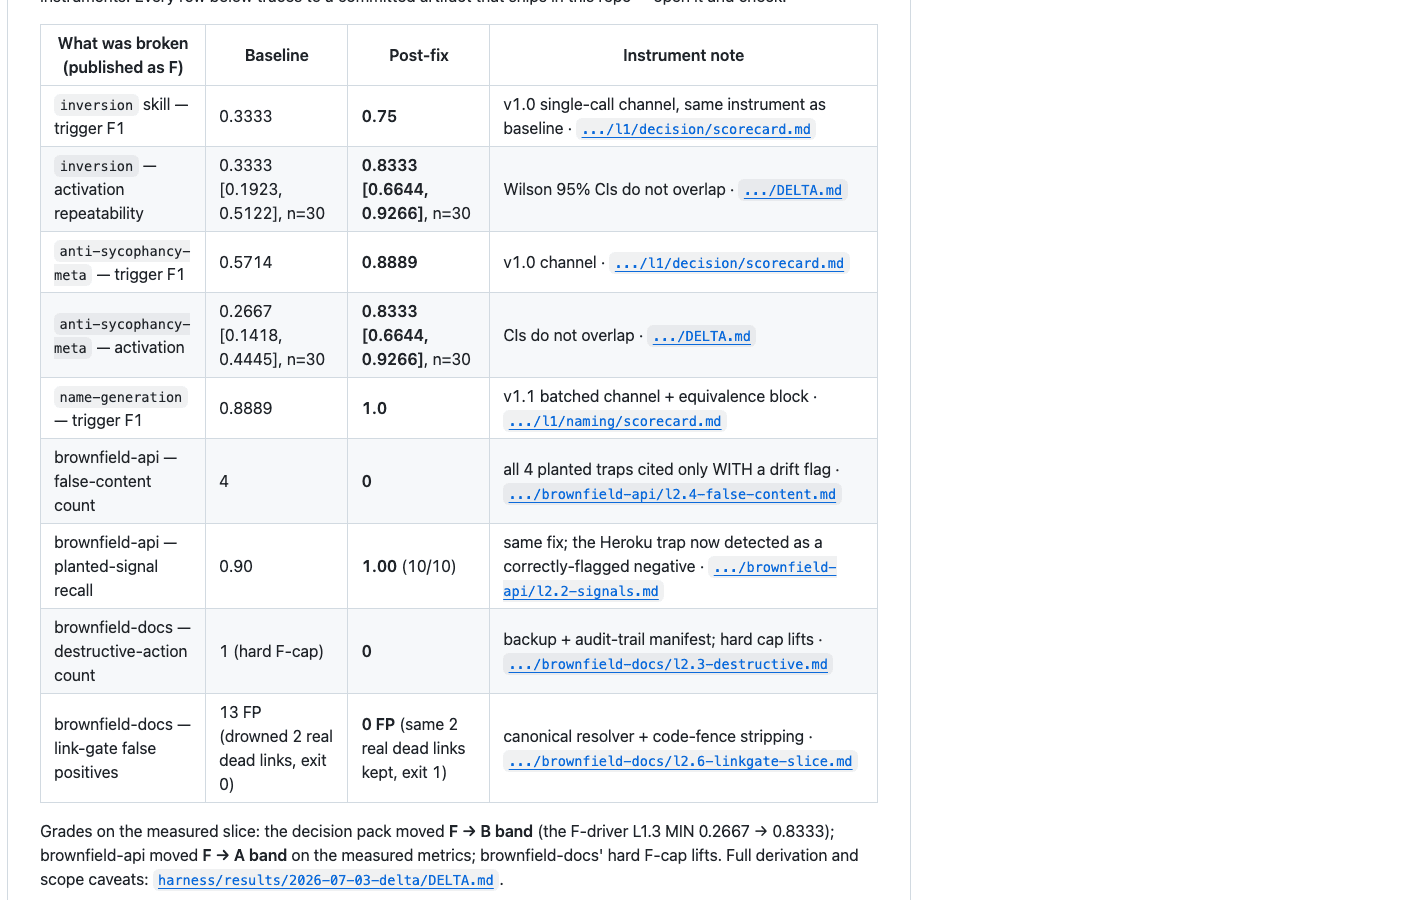
The activation row carries the weight. For the inversion skill the baseline interval is [0.1923, 0.5122] and the delta interval is [0.6644, 0.9266]; the two ranges are disjoint. At the trigger level, three skills moved on the same run: inversion from 0.3333 to 0.75, anti-sycophancy-meta from 0.5714 to 0.8889, and name-generation from 0.8889 to 1.0. Twenty-two skills are published this way in total, twelve decision, six naming and four design.
One trigger score is published as a drop: disconfirming-evidence-first, from 0.9091 to 0.8889. It stays in the public record because the spec that defines the metric was committed before the run, so re-baselining after the fact was off the table.
The drop also deserves a correction I owe the reader. That pair is a cross-channel comparison. The baseline was measured on the single-call channel and the delta on the batched channel, while the improvement rows above deliberately use same-channel figures. DELTA.md labels the channel; the README does not. So the honest reading is that the loss is real as recorded and the comparison is not like for like.
The quality discipline is not executable. There is no CI, no test framework and no pre-commit hook. The pre-registration guarantee, the release gate and the 534-line validation checklist are all procedures a human or an agent performs, and the "release verifier" the README credits is a runbook step rather than a program.
The pre-registration margin is 56 minutes. The spec commit at 14:14:09 on 2026-07-03 does precede the first results commit at 15:10:41, and that order is git-verifiable. The delta's prediction plan lived outside the repository and was committed afterward, which DELTA.md itself records as operator-attested rather than git-provable.
v0.20.1 has not shipped. An external field trial on 2026-07-13 filed 11 defects; ten were dispositioned into a v0.20.1 that does not exist, and plugin.json still pins 0.20.0.
Two of those defects are safety findings, both unfixed. The generated .mcp.json runs a third-party MCP server through npx unconditionally, rated blocker by the trial. The generated settings.json ships a 15-entry command allowlist, rated major. A proposals-only path exists, and it fires only when the target project already has its own credential-governance gate.
Batched-channel intervals ship flagged "nominal." The trial records carry no batch identifier, so batch interleave cannot be audited. The README says so.
The project has caught itself. Its own changelog entry of 2026-08-25 records four shipped claims that were false on the day of that pass.
The public claim surface is narrower than the work. The public repository is a built snapshot, and the later and larger measurement study is excluded from it, so what a visitor can verify is the 2026-07-03 delta.
Make the discipline run itself: the self-test suites, the spec-precedes-results git check and a documentation-count check as a GitHub Action instead of a checklist step.
Let a blocker-severity defect block the next release mechanically, or stop using the severity label.
Commit the prediction plan at the start of the work and put a day between the spec and the run, rather than compressing spec, fixtures, baseline, fixes, re-measure and launch into a 6.5-hour window.
Markdown templates and prompt specs, shell and Python runners for the harness and the scrub gate, a Claude Code plugin manifest for the one-command install, MIT license.
DirectiveForge generates AI workflow kits for Claude Code and Cursor, then measures whether the skills it generated actually fire. On the pre-registered harness in the public repo, skill activation went from 0.33 to 0.83 with non-overlapping Wilson 95% confidence intervals over 30 runs per skill, measured for the v0.20.0 release on 2026-07-03. It ships MIT, and the raw per-trial records sit in the repo next to the summaries, so a stranger can recompute the numbers instead of trusting them.
Code and site: github.com/directiveforge/directiveforge and directiveforge.com.
A workflow kit you can check instead of trust
The rules and skills people bolt onto coding agents mostly ship on feel. Someone writes a prompt, it reads better, it gets committed. I wanted to hand a kit to another developer with a published number attached to each piece: how often the skill fires on the inputs it should, and how often it stays quiet on the inputs it should not.
That meant two jobs, and the second one is the hard one. Generate the kit. Then prove the generated kit behaves, with evidence someone else can check without my help.
What the work had to fit around
I ran it as a private lab before any of it was public. First commit 2026-03-29; 144 commits by the git check on 2026-07-06, and the public repository is a single squashed snapshot because the evidence had to be scrubbed before it could ship.
The evidence is bulky. The lab tree tracks 1,979 files and 428 MB on disk, and 296 MB of that is recorded measurement output under
harness/results/. Those files are the product, and they are also full of local paths and client material, so redaction was a build step rather than a cleanup pass.The measurement work was also compressed. The harness release, the delta run and the launch release all landed inside one day, 2026-07-03, across 21 commits between 14:14:09 and 20:41:01. That compression shows up again in the limits below.
What I built
The generator reads a codebase and writes the workflow files for it: rules, skills, commands, agents, MCP configuration and memory, installed into Claude Code or Cursor with one command. In the recorded runs it writes between 29 and 44 files, and every one of those runs left a manifest in the repo.
Around the generator sits the part that took the time.
The measurement is fixed before the run. The spec that defines each metric is committed before any result is collected, and the answer keys live in frozen fixture cards the generator never sees. Per-prompt and per-trial records are committed alongside the aggregates. That design was tested against me: an independent audit re-derived the 12 decision-skill trigger scores from the 120 raw router records and got 12 of 12 exact, with an identical pack-level F1 of 0.9661. F1 combines precision and recall into one number, which stops a skill from looking better by firing on everything.
Every rate ships as an interval, not a point. Each skill is run 30 times and reported as a Wilson 95% confidence interval, a range the true rate is likely to sit inside. A change only counts as an improvement when the two ranges do not overlap. The same audit recomputed all 14 published intervals from their own counts and matched them to four decimal places, and reproduced every activation count from the per-trial records.
The model that grades is graded first. Part of the scoring is done by a model reading outputs against a rubric. Before its verdicts counted, a second model re-judged the same outputs blind against a human-scored key: 18 of 20 exact, 20 of 20 within one point.
Publishing the evidence without leaking anything. The scrub gate fails the build on any hit, a hash bridge lets a reader confirm that a redacted file is the file it claims to be (67 artifacts carry one), and the scanner ships publicly while the list of identifying patterns stays on my machine. The public repository is a built snapshot produced by that pipeline, not a copy of the lab.
What the numbers came out at
All figures below are from the 2026-07-03 delta run and its committed artifacts in the public repo.
The activation row carries the weight. For the
inversionskill the baseline interval is [0.1923, 0.5122] and the delta interval is [0.6644, 0.9266]; the two ranges are disjoint. At the trigger level, three skills moved on the same run:inversionfrom 0.3333 to 0.75,anti-sycophancy-metafrom 0.5714 to 0.8889, andname-generationfrom 0.8889 to 1.0. Twenty-two skills are published this way in total, twelve decision, six naming and four design.The regression I published, and what the README got wrong
One trigger score is published as a drop:
disconfirming-evidence-first, from 0.9091 to 0.8889. It stays in the public record because the spec that defines the metric was committed before the run, so re-baselining after the fact was off the table.The drop also deserves a correction I owe the reader. That pair is a cross-channel comparison. The baseline was measured on the single-call channel and the delta on the batched channel, while the improvement rows above deliberately use same-channel figures.
DELTA.mdlabels the channel; the README does not. So the honest reading is that the loss is real as recorded and the comparison is not like for like.Where it currently falls short
DELTA.mditself records as operator-attested rather than git-provable.plugin.jsonstill pins 0.20.0..mcp.jsonruns a third-party MCP server throughnpxunconditionally, rated blocker by the trial. The generatedsettings.jsonships a 15-entry command allowlist, rated major. A proposals-only path exists, and it fires only when the target project already has its own credential-governance gate.What I would change
Stack
Markdown templates and prompt specs, shell and Python runners for the harness and the scrub gate, a Claude Code plugin manifest for the one-command install, MIT license.
Discuss an AI workflow or eval build